FOR HANDS-ON TEAMS
Your stack. Full control.
Dedicated bare-metal servers for teams that want to run and manage their own environment.
- Direct access to the hardware
- Your frameworks and software stack
- Your team manages the environment
GPU RENTAL + FRONTIER MODEL ACCESS
Rent hardware to run your own workloads, or use Claude, GPT, Gemini and GLM through AIM. Choose the service you need.
Dedicated hardware. Pay by GPU-hour.
Claude, GPT & more. Pay by token.
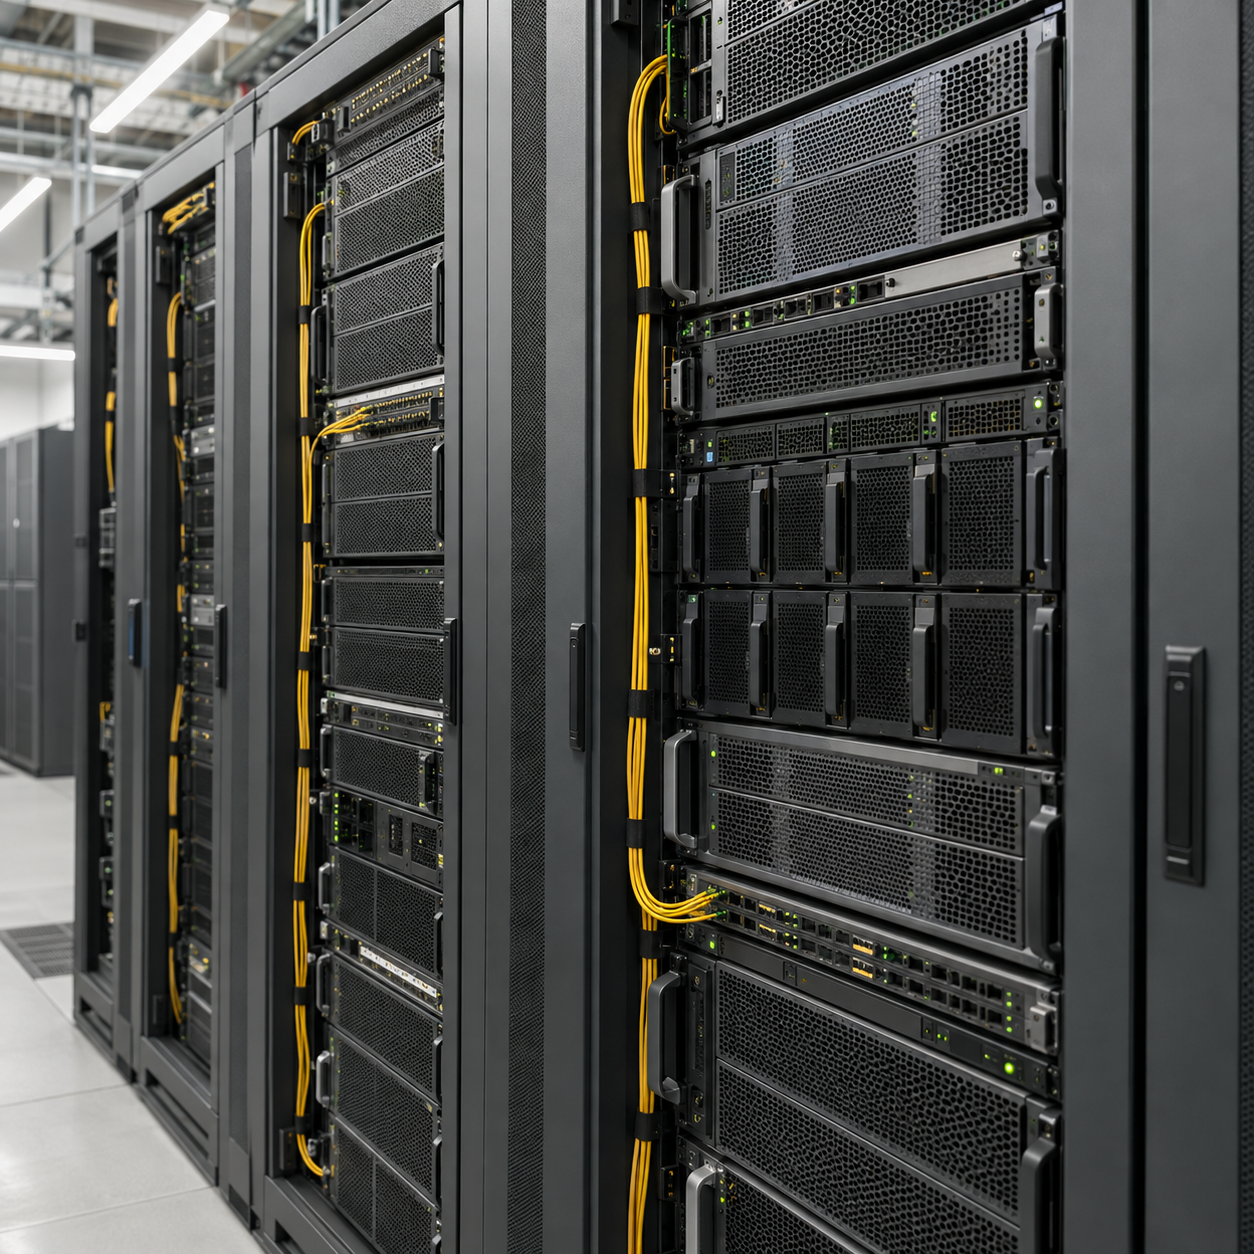
Rent dedicated B300 GPUs in Japan. Run your own models and software, with bare-metal access or a managed cluster.
Use Claude, GPT, Gemini, GLM and more in your applications. Pay for the tokens you use, without renting GPUs.
FRONTIER MODEL ACCESS
Bring Claude, GPT, Gemini, GLM and more into your applications. Access them through one AIM API and pay for the tokens you use. No GPU rental required.


 GPT


 GLM
And more, through AIM.
AIM GPU RENTAL · HOSTED IN JAPAN
Dedicated hardware for your own training and inference workloads, billed by GPU-hour. Choose bare-metal servers or a managed cluster.
Dedicated bare-metal servers for teams that want to run and manage their own environment.
A managed cluster for teams that want support with the infrastructure behind their training and inference.
GPU RENTAL · THE HARDWARE
Watch the B300 grow from a single GPU into a complete infrastructure. Pause at any point, or choose a stage below.
The hardware behind your next run.
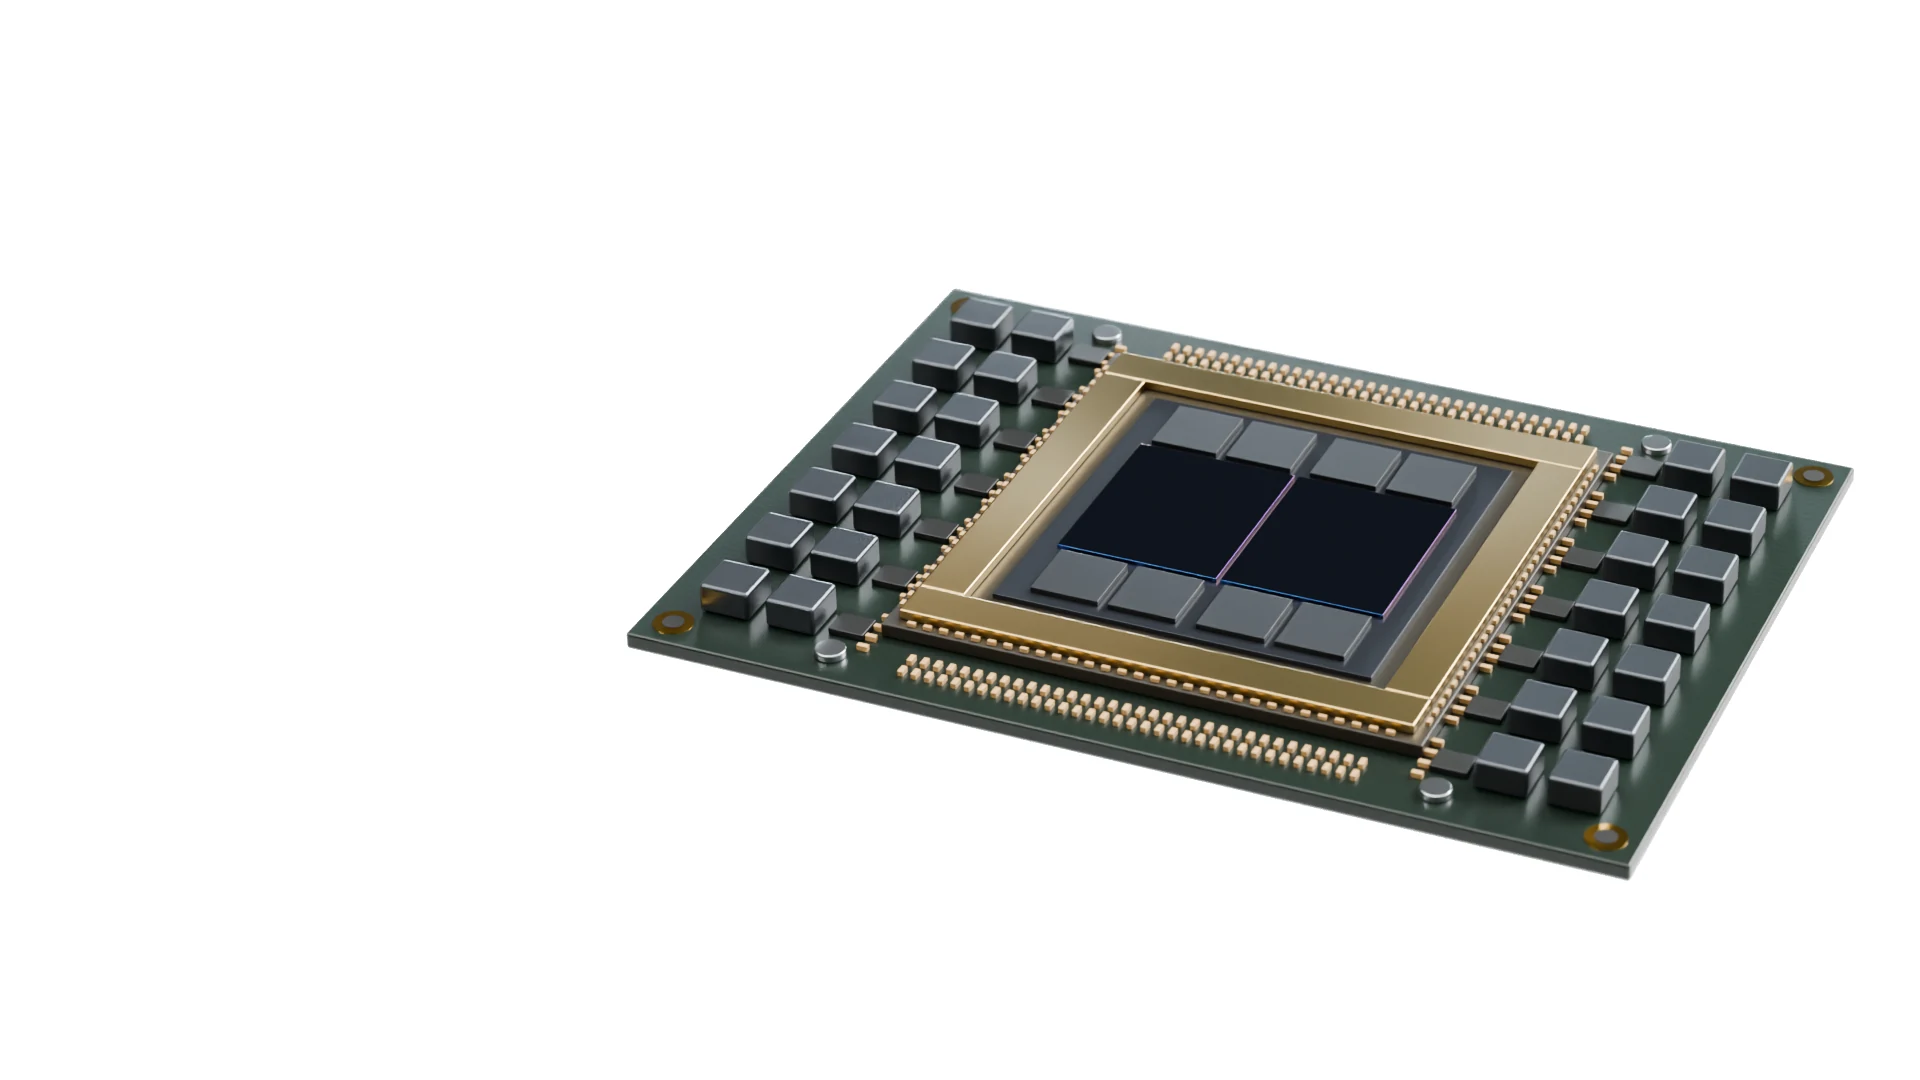
NVIDIA BLACKWELL ULTRA
288 GB of HBM3e memory on each GPU, for the models and workloads your team wants to run.
EIGHT GPUS. ONE SYSTEM.
Eight B300 GPUs connected through NVLink in every server. Run on dedicated hardware with your choice of software.
THE CONNECTED CLUSTER
Bring compute, storage and networking together. We help shape the cluster around your training or inference workload.
HOSTED IN JAPAN
Your B300 infrastructure, hosted in Japan. One team to discuss the hardware, deployment and ongoing support you need.
BASED IN JAPAN. BUILT FOR YOUR TEAM.
AI Management K.K. supports your AI work with dedicated B300 compute in Japan and token-based access to third-party AI models. Tell us what you are building; we will work through the right service with you.
FROM FIRST CONVERSATION TO FIRST RUN
Your application, model or compute needs, expected usage and timeline.
We discuss the right service, confirm availability and work through pricing.
Agree the technical setup and onboarding steps for your selected service.
YOUR NEXT RUN STARTS HERE
GPU rental, access to AI models, or both. Tell us what you need and when you want to start.
Email our team